NEWS
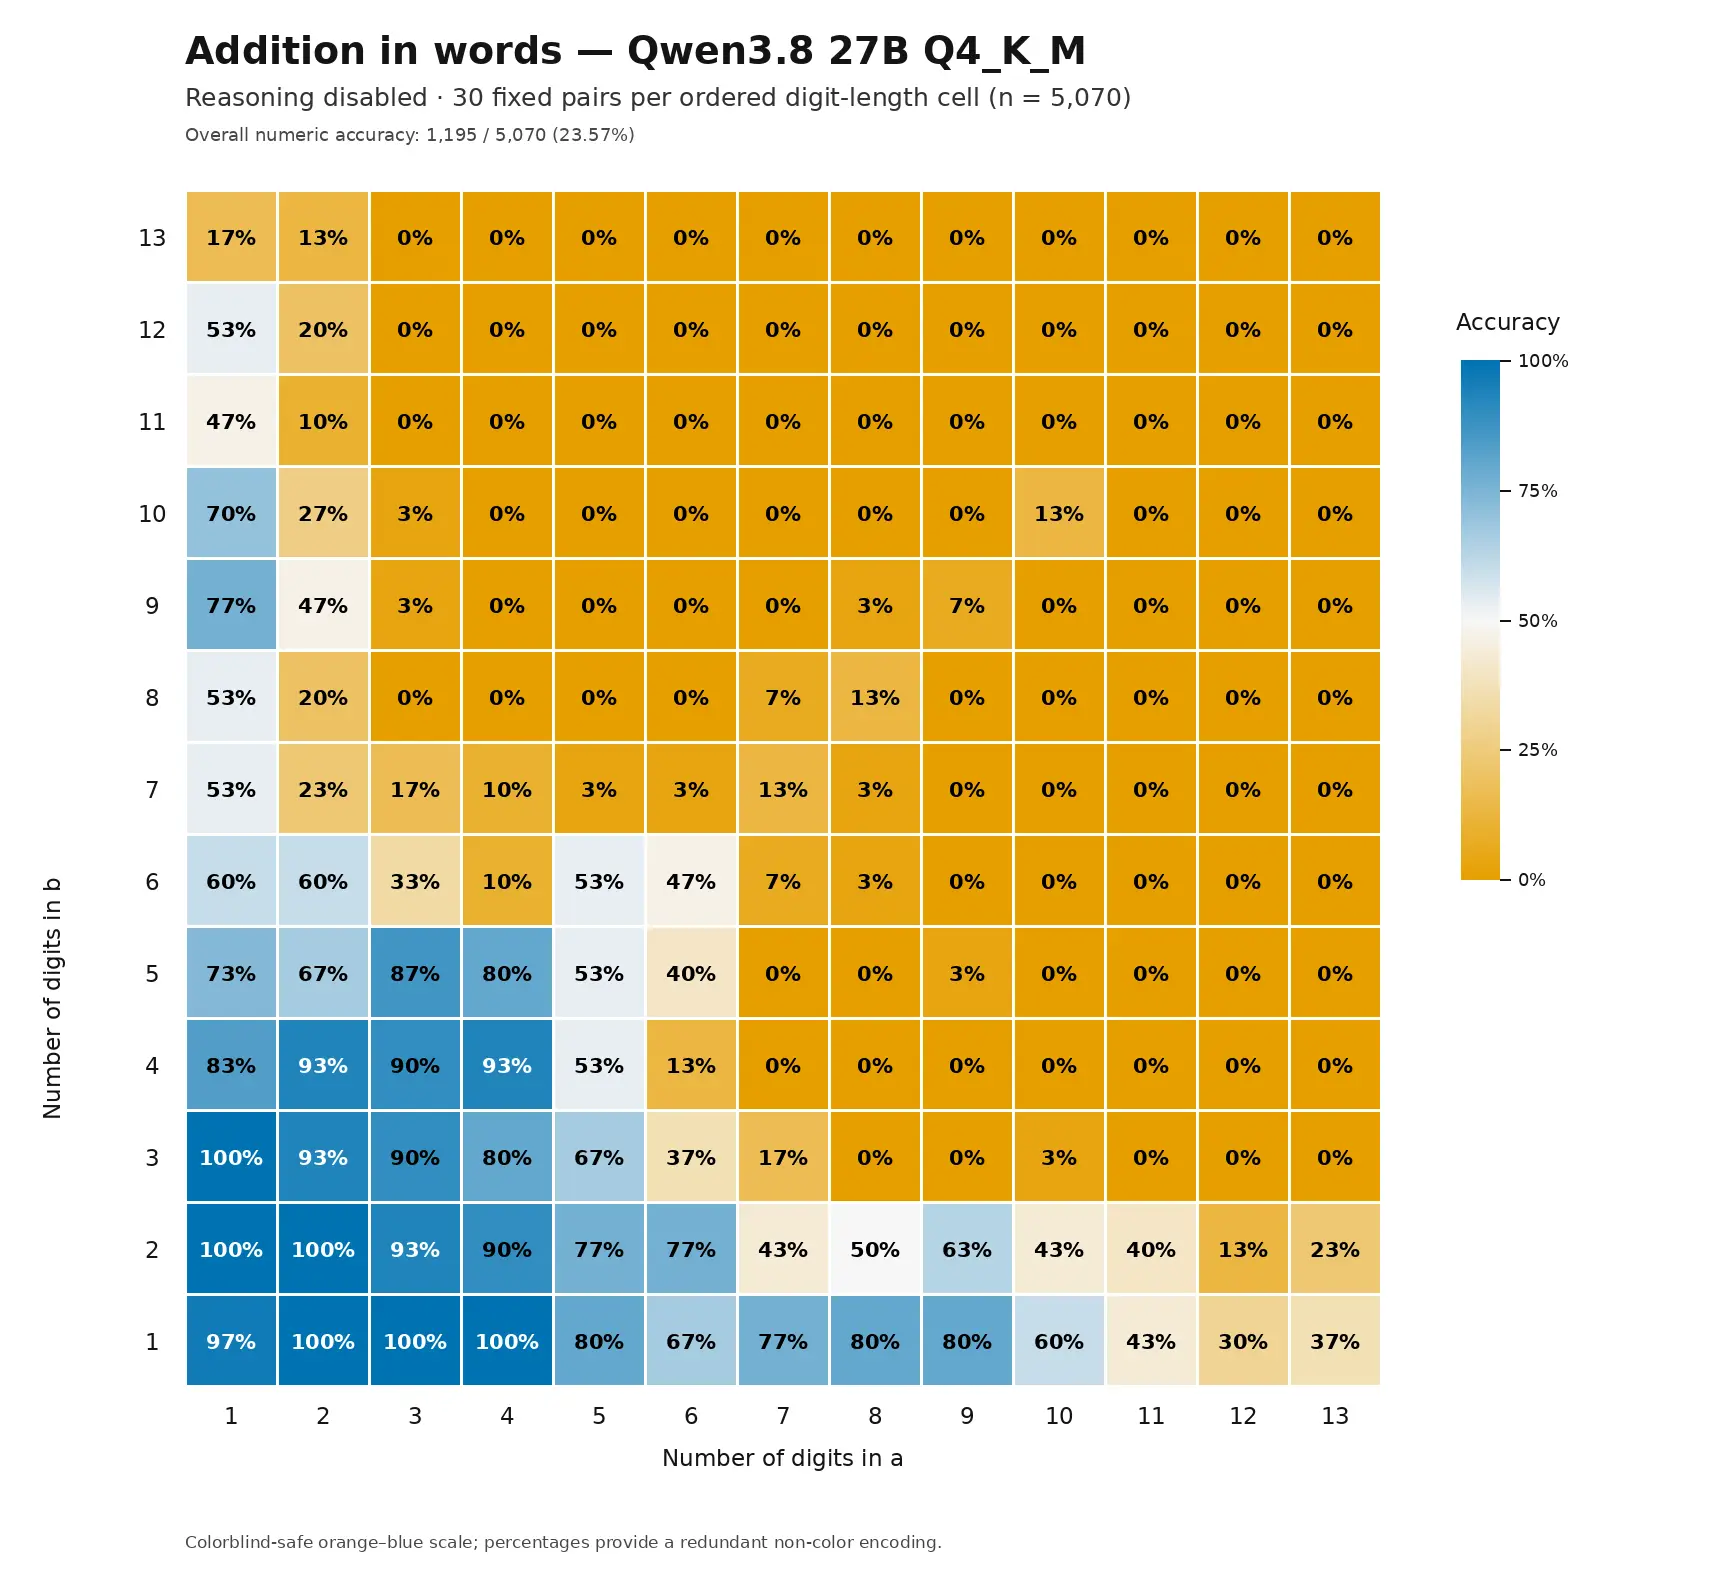 Qwen3.8-27B shows low performance in word-based addition testIn the comparison performed on local hardware, with reasoning disabled, the model’s accuracy in adding large numbers in word form remained at 23.57%. With reasoning enabled, the model produced the correct result in 167 of 169 trials. This is a news summary compiled for the AiPulse newsletter — not the original article. The original article is at simonwillison.net. Read the original article AI Critique → English (automatic translation) |