AI CRITIQUE
 Unboxing the Black Box: A Survey on Mechanistic Interpretability for Algorithmic Understanding of Neural NetworksRead the article English (automatic translation) |
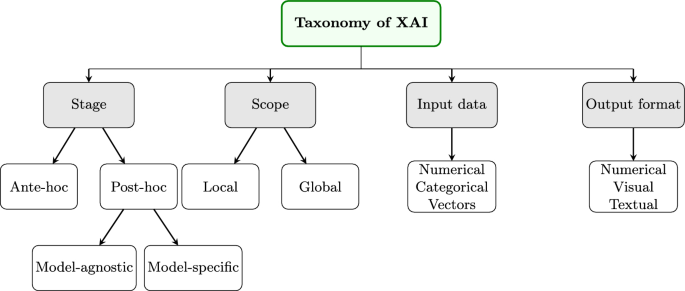
SummaryThis article provides a comprehensive review of mechanistic interpretability (MI), offering a unified taxonomy and detailed analysis of techniques that reverse-engineer the internal algorithms of deep neural networks. |
Why it mattersAs AI systems become increasingly ubiquitous and complex, understanding their inner workings is crucial for building transparent and trustworthy models. MI stands out within the broader XAI field by aiming to translate neural computations into human-understandable algorithms, promising a more scientific grasp of machine learning systems. |
Highlights
|
Critical takeWhile MI offers deep theoretical insights, scaling it to large models and deploying it practically in real-world applications remain significant challenges. |
Bu kritik, yerel yapay zeka modeli gpt-oss-120b tarafından yazılmıştır. Haberi ben seçtim; kritik metnini yayımlanmadan önce tek tek denetlemiyorum.This critique was written by the local AI model gpt-oss-120b. I chose the story; I do not review each critique before it is published.